DeepSeek V4.1 Flash 1017 Is Live on A2Agent: Same Price, Stronger Agent Scores
A2Agent Team · 2026-10-17T00:00:00Z
DeepSeek released V4.1-Flash-1017 on October 17, 2026. It's a new checkpoint of V4.1 Flash, which first shipped on September 10, and it replaces that build everywhere: the DeepSeek website, the app and the API. The API name stays deepseek-flash, the price is unchanged and the calling method is the same, so existing code picks up the new model without any changes.
The scores went up on every benchmark DeepSeek published, by 2.0 to 11.1 points. DeepSeek also says the model finishes tasks faster and writes shorter outputs, which lowers the cost of each task on top of the unchanged token price.
The 1017 build is now live on A2Agent as deepseek-v4.1-flash-1017, at the same price as our existing deepseek-v4.1-flash.
Quick answer
- Model: DeepSeek-V4.1-Flash-1017, served as
deepseek-flash - Price on DeepSeek's API, per million tokens: $0.15 input, $0.60 output and $0.003 for cache hits off-peak; double that at peak hours
- 1M-token context, up to 384K output tokens, native image input
- Biggest gains over the September build: Terminal-Bench 4.0 (+11.1), ProgramBench (+8.8), Apex Bench (+7.5) and HLE (+5.8)
- DeepSWE v1.1: 77.0, ahead of Claude Opus 5 (74.0) and GPT-5.6 Sol (73.0)
- Live on A2Agent now as
deepseek-v4.1-flash-1017, at $0.102 input and $0.378 output per million tokens
Benchmarks
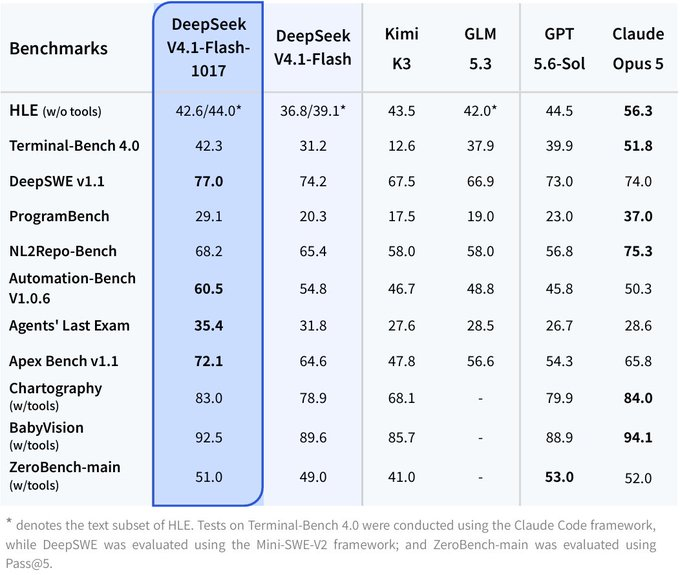
Here is the new build against the September 10 build, using DeepSeek's published numbers:
| Benchmark | V4.1 Flash (Sep 10) | V4.1 Flash 1017 | Change |
|---|---|---|---|
| HLE (no tools) | 36.8 | 42.6 | +5.8 |
| Terminal-Bench 4.0 | 31.2 | 42.3 | +11.1 |
| DeepSWE v1.1 | 74.2 | 77.0 | +2.8 |
| ProgramBench | 20.3 | 29.1 | +8.8 |
| NL2Repo-Bench | 65.4 | 68.2 | +2.8 |
| Automation-Bench v1.0.6 | 54.8 | 60.5 | +5.7 |
| Agents' Last Exam | 31.8 | 35.4 | +3.6 |
| Apex Bench v1.1 | 64.6 | 72.1 | +7.5 |
| Chartography (with tools) | 78.9 | 83.0 | +4.1 |
| BabyVision (with tools) | 89.6 | 92.5 | +2.9 |
| ZeroBench-main (with tools) | 49.0 | 51.0 | +2.0 |
On the text-only subset of HLE, the score went from 39.1 to 44.0. DeepSeek ran Terminal-Bench 4.0 in Claude Code, DeepSWE in the Mini-SWE-V2 harness, and ZeroBench-main at Pass@5.
In the same table, this Flash-tier model beats Claude Opus 5 and GPT-5.6 Sol on four agent benchmarks: DeepSWE v1.1 (77.0), Automation-Bench (60.5), Agents' Last Exam (35.4) and Apex Bench (72.1). Opus 5 still leads on HLE, Terminal-Bench, ProgramBench, NL2Repo-Bench, Chartography and BabyVision, and GPT-5.6 Sol leads ZeroBench-main.
Cost per task
Token prices don't tell you what a task costs, because models differ in how many tokens they burn to finish. DeepSeek's DeepSWE chart plots pass rate against the average cost of each task:
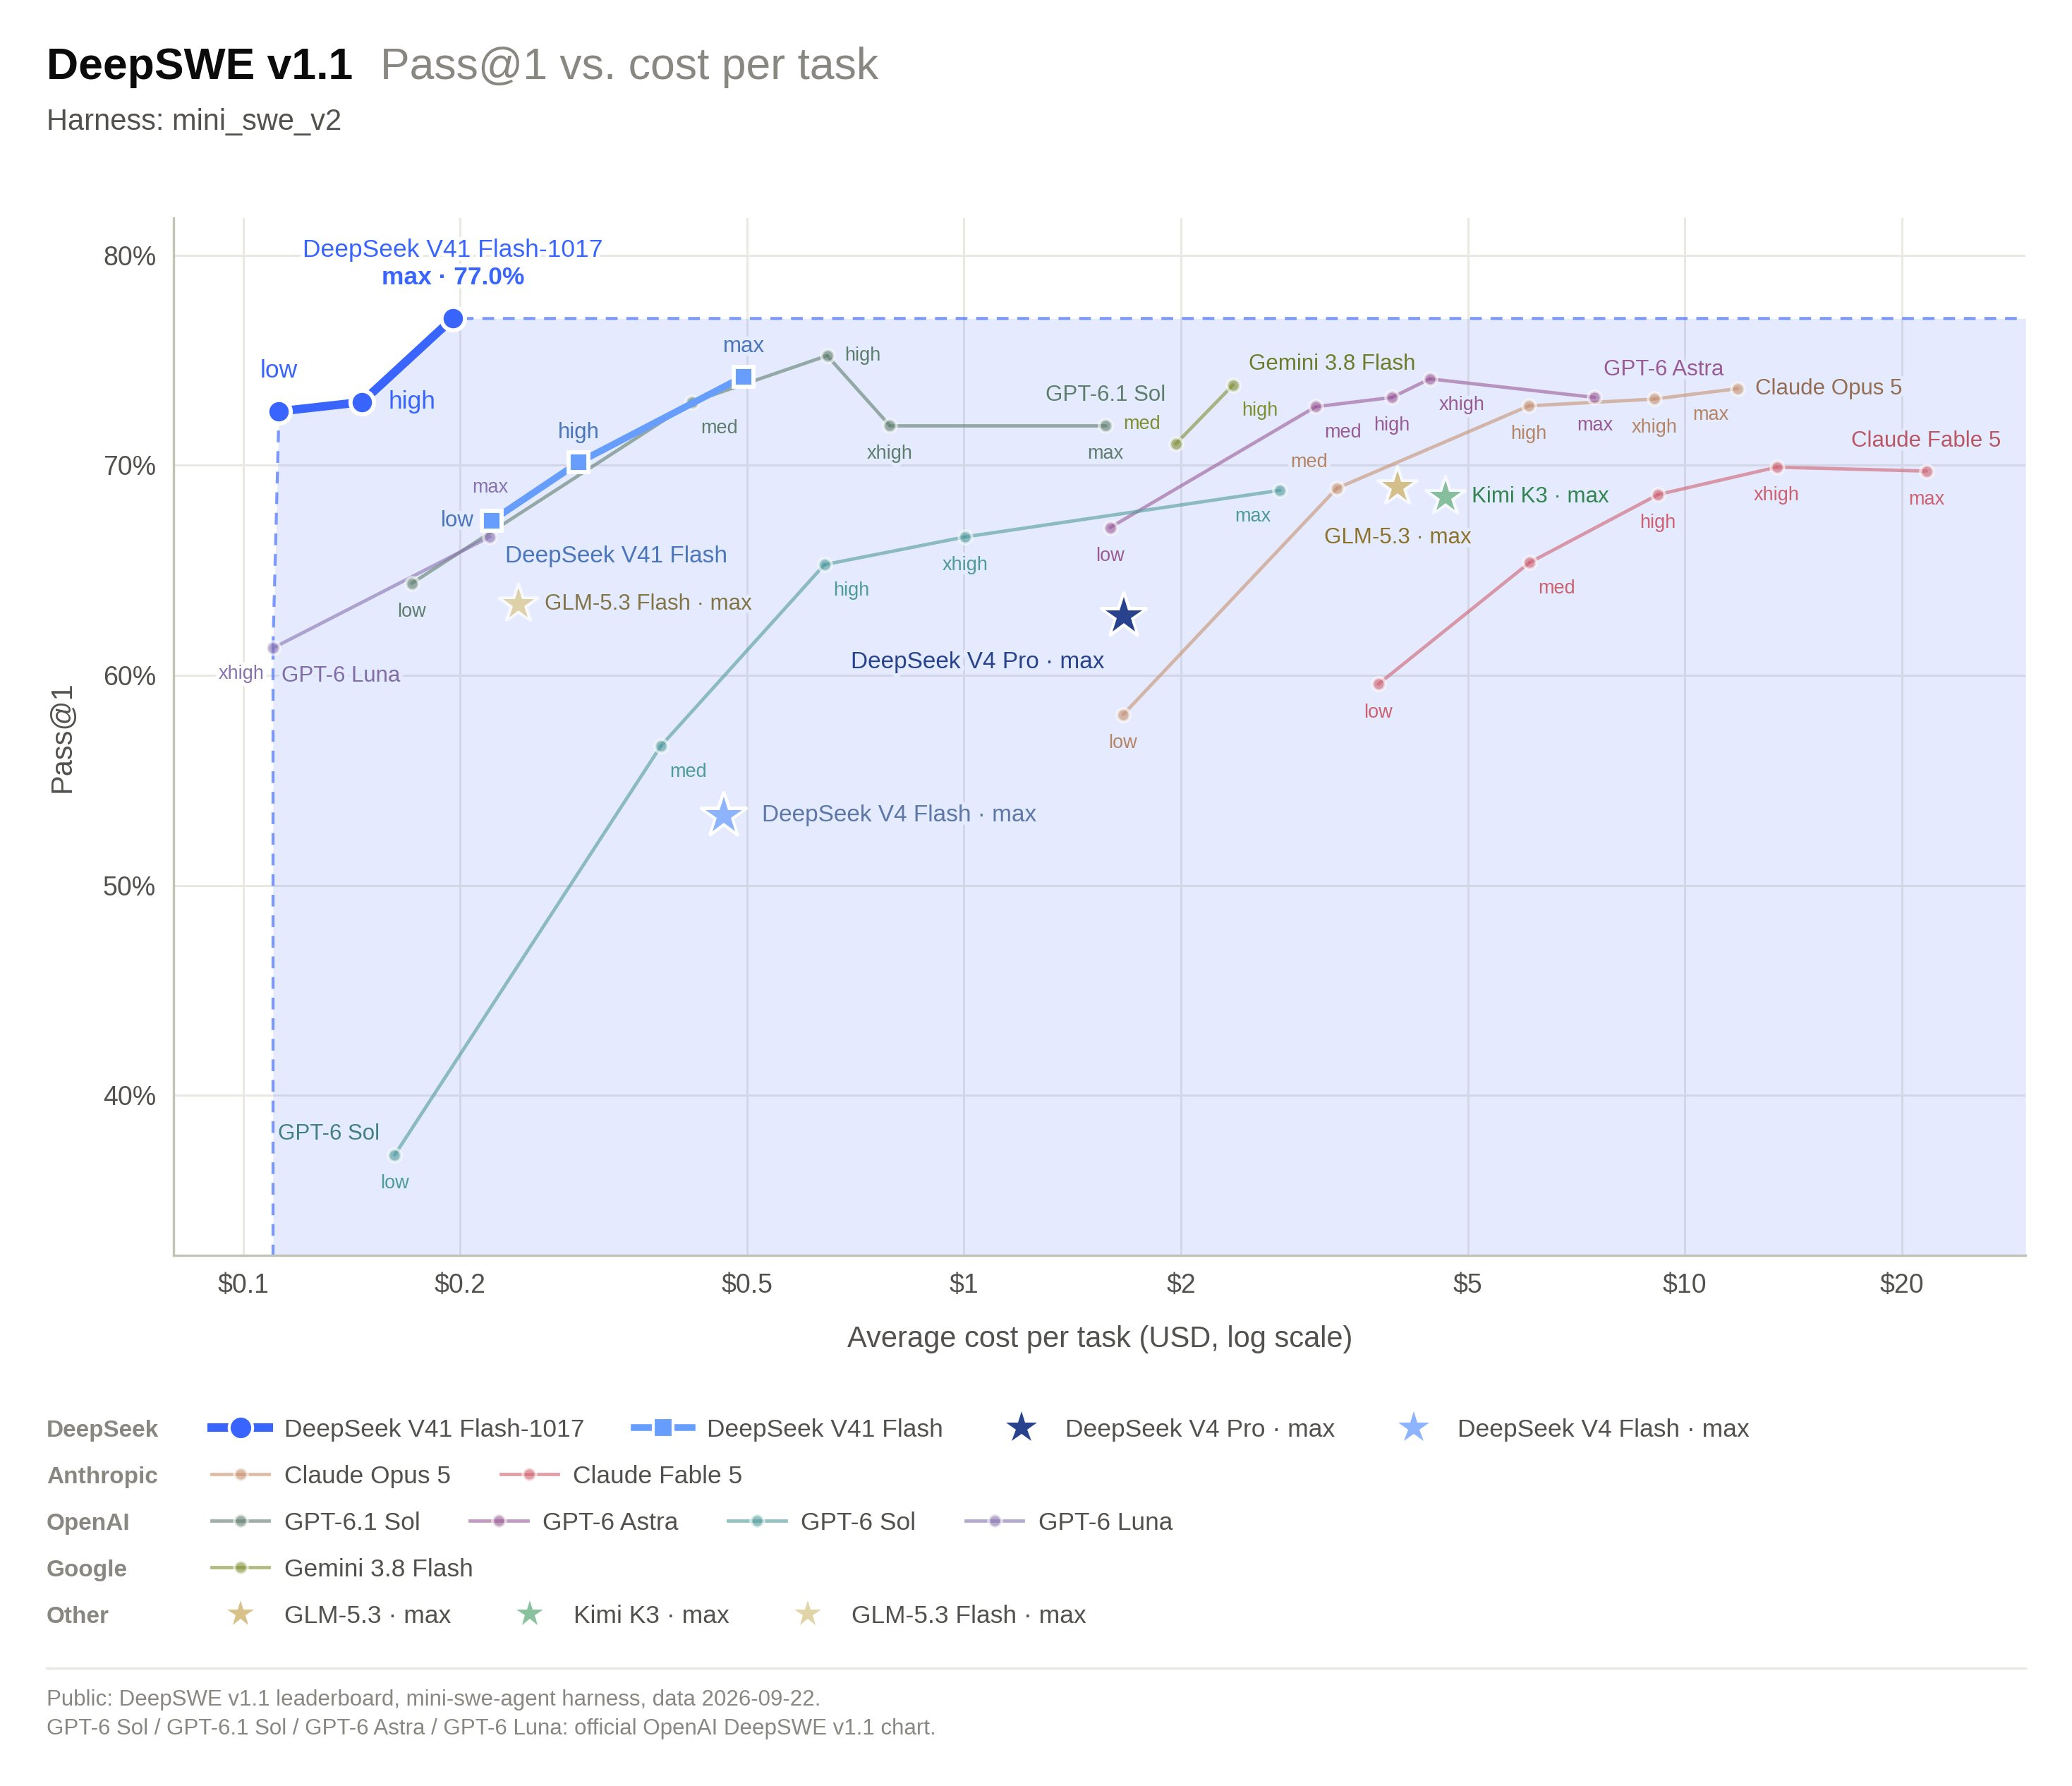
Reading the chart, the 1017 build at max effort solves 77.0% of tasks for roughly $0.20 each. The September build at max effort reached 74.2% for roughly $0.50. At low effort it still scores above 72%, for about $0.11 a task. The nearest competitor on pass rate is GPT-6.1 Sol at about 75% for roughly $0.65, and Claude Opus 5 lands around 73% to 74% at $6 to $12 per task.
Why it's cheaper to run
DeepSeek says 1017 takes less time per task and writes shorter outputs than the September build. Output tokens cost four times as much as input tokens, so shorter outputs cut the cost of each task directly.
Cache reads are the other half. V4.1 Flash stores its main KV cache in FP4, which shrinks global KV memory to roughly a quarter of the previous Flash generation, and cache hits cost $0.003 per million tokens off-peak. In a long agent loop the model rereads the same context on every turn, so most input tokens are cache hits, and at that price they barely register on the bill.
Pricing
DeepSeek's prices for deepseek-flash, per million tokens:
| Off-peak | Peak | |
|---|---|---|
| Input, cache hit | $0.003 | $0.006 |
| Input, cache miss | $0.15 | $0.30 |
| Output | $0.60 | $1.20 |
Peak hours are 01:00 to 04:00 and 06:00 to 10:00 UTC, Monday to Friday, excluding Chinese public holidays. Every other hour is off-peak.
Under the hood
V4.1 Flash is a sparse mixture-of-experts model and the first DeepSeek model built on a Causal Encoder-Decoder architecture. It has a 552B-parameter backbone and activates 8B parameters when reading input and 16B when generating output. Vision and text were trained together from the start of pre-training, so image input is native.
On the API it supports thinking mode (the default) and non-thinking mode, JSON output, tool calls and vision. The older names deepseek-v4-flash and deepseek-v4-flash-vision-exp still work and now route to V4.1 Flash.
DeepSeek says it tuned 1017 for agent frameworks including DeepSeek Harness, Tencent CodeBuddy and WorkBuddy, and recommends DeepSeek Harness 0.2.1-rc.1 or later.
Also new: Search and Fetch APIs
Alongside the model, DeepSeek opened two tool APIs on api.deepseek.com. Search (POST /v1/tools/search) returns ranked web results for a query, and Fetch (POST /v1/tools/fetch) returns a single page as Markdown. Each costs $0.75 per 1,000 successful requests. Calls made through DeepSeek Harness, Claude Code or Codex are free until November 1, 2026.
Use it on A2Agent
V4.1-Flash-1017 is now live on A2Agent. Call it as deepseek-v4.1-flash-1017 for $0.102 per million input tokens and $0.378 per million output tokens, the same price as deepseek-v4.1-flash, with the same key you use for every other model on A2Agent. If you're on deepseek-v4.1-flash today, switching is a one-line change to the model name.
With the OpenAI SDK:
from openai import OpenAI

client = OpenAI(
    api_key="YOUR_API_KEY",
    base_url="https://api.a2agent.me/v1",
)

response = client.chat.completions.create(
    model="deepseek-v4.1-flash-1017",
    messages=[{"role": "user", "content": "Hello"}],
)

print(response.choices[0].message.content)
To run it in Claude Code, set ANTHROPIC_BASE_URL to https://api.a2agent.me and ANTHROPIC_MODEL to deepseek-v4.1-flash-1017. The Models page has current prices and details. New accounts get $5 in free credit, so you can sign up and try it today.
Sources
- DeepSeek-V4.1-Flash-1017 Update (DeepSeek API docs)
- Models and pricing (DeepSeek API docs)
- DeepSeek announcement on X
- DeepSeek V4.1 Flash 1017 (OpenRouter)
- DeepSeek Just Released V4.1-Flash-1017 (MarkTechPost)