Cheapest AI Models for Code in 2026: Price Comparison on A2Agent
A2Agent Team · 2026-09-29T00:00:00Z
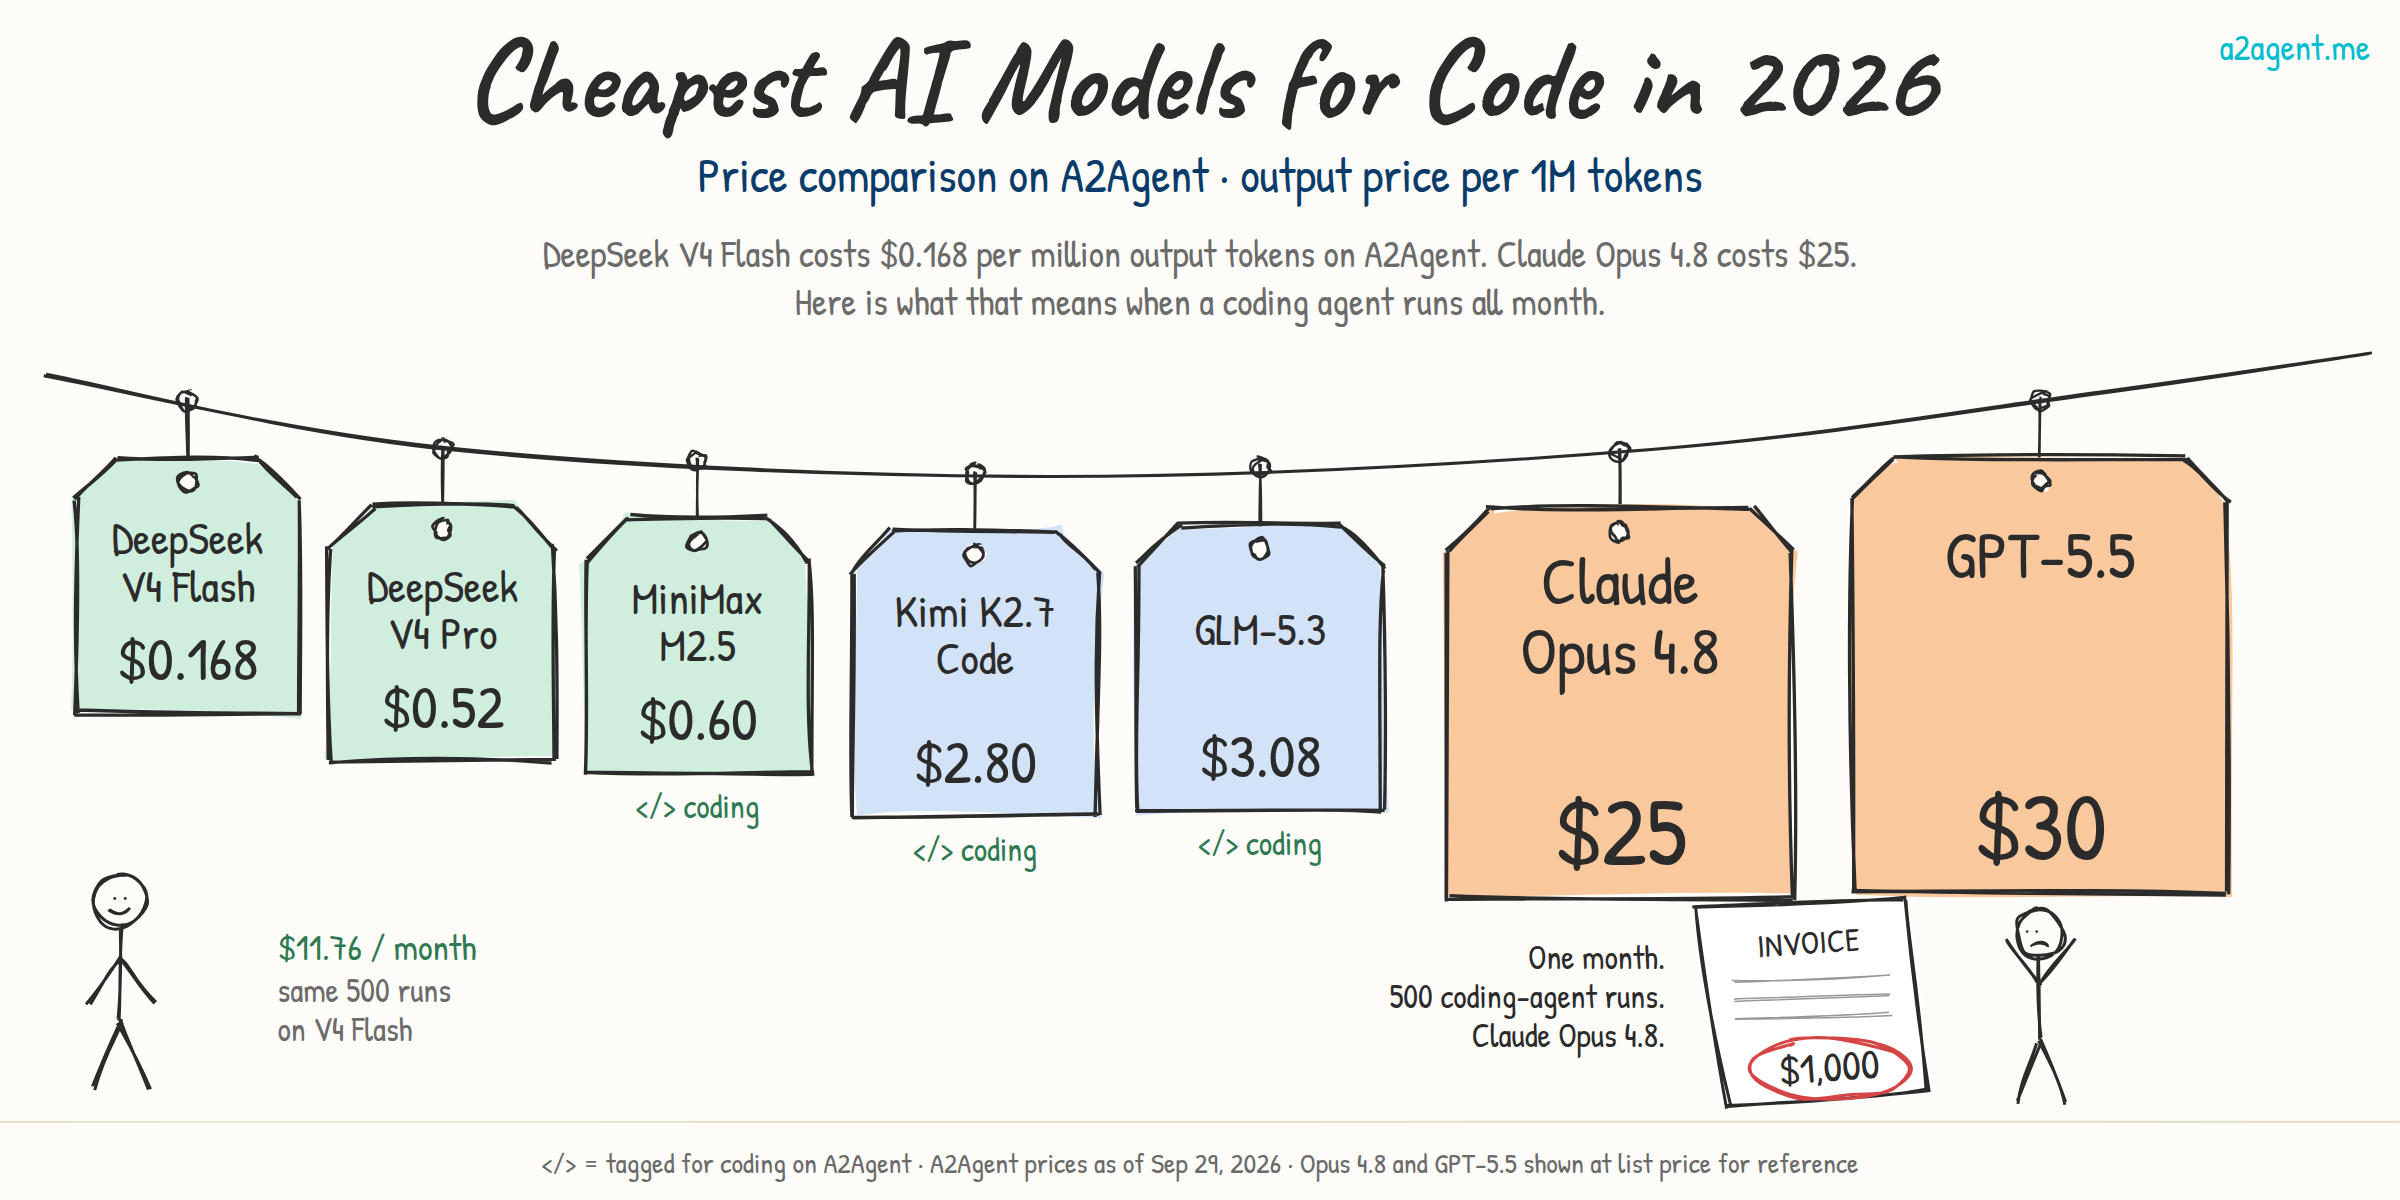
Say a coding agent runs 500 times a month. Each run reads about 200,000 tokens of repository context and writes about 40,000 tokens of plans, diffs and test fixes. On Claude Opus 4.8 at list price, that month costs $1,000. The same 500 runs on DeepSeek V4 Flash through A2Agent cost $11.76.
Most of that gap is the price per million tokens. Some of it comes from the way coding agents use tokens, which looks very different from a chat session. The prices below are live A2Agent prices from September 29, 2026, for every model we sell.
Quick answer
The cheapest model on A2Agent is DeepSeek V4 Flash: $0.084 per million input tokens and $0.168 per million output, with a 1M-token context window. DeepSeek's own price is $0.14 / $0.28, so that is 40% off.
Other prices worth knowing:
- MiniMax M2.5 and M2.7 are the cheapest models tagged for coding, at $0.15 / $0.60 (half of MiniMax's official price).
- DeepSeek V4 Pro is the cheapest strong reasoning model, at $0.261 / $0.522 with a 1M context.
- GLM-5.2 ($0.84 / $2.64) and GLM-5.3 ($0.98 / $3.08) are tagged for coding and have a 1M context. Kimi K2.7 Code ($0.665 / $2.80) is also tagged for coding and has 256K.
- Claude Opus 4.8 lists at $5 / $25 and GPT-5.5 at $5 / $30 on their vendors' own APIs. We don't sell either. Per output token, GPT-5.5 costs about 180 times what DeepSeek V4 Flash does.
Full price table: 21 models on A2Agent
Prices are in US dollars per million tokens, sorted by output price. "Official" is the vendor's own list price. "Tag" is the category shown in the A2Agent model catalog.
| # | Model | Tag | A2Agent input | A2Agent output | Official input / output | Discount | Context |
|---|---|---|---|---|---|---|---|
| 1 | DeepSeek V4 Flash | reasoning | $0.084 | $0.168 | $0.14 / $0.28 | 40% | 1M |
| 2 | GLM-5.3 Flash | vision | $0.105 | $0.35 | $0.15 / $0.50 | 30% | 1M |
| 3 | Qwen3.8 Flash | vision | $0.135 | $0.423 | $0.15 / $0.47 | 10% | 1M |
| 4 | DeepSeek V4.1 Flash | — | $0.136 | $0.504 | $0.17 / $0.63 | 20% | — |
| 5 | DeepSeek V4 Pro | reasoning | $0.261 | $0.522 | $0.435 / $0.87 | 40% | 1M |
| 6 | Qwen3.7 Flash | vision | $0.14 | $0.56 | $0.20 / $0.80 | 30% | 1M |
| 7 | MiniMax M2.5 | coding | $0.15 | $0.60 | $0.30 / $1.20 | 50% | 1M |
| 8 | MiniMax M2.7 | coding | $0.15 | $0.60 | $0.30 / $1.20 | 50% | 200K |
| 9 | MiniMax M3 | agent | $0.15 | $0.60 | $0.30 / $1.20 | 50% | 1M |
| 10 | Qwen3.6 Flash | vision | $0.16 | $0.96 | $0.20 / $1.20 | 20% | 1M |
| 11 | GLM-5 | agent | $0.60 | $1.92 | $1.00 / $3.20 | 40% | 200K |
| 12 | Kimi K2.5 | vision | $0.42 | $2.10 | $0.60 / $3.00 | 30% | 256K |
| 13 | Qwen3.5 Plus | vision | $0.35 | $2.10 | $0.50 / $3.00 | 30% | 1M |
| 14 | GLM-5.2 | coding | $0.84 | $2.64 | $1.40 / $4.40 | 40% | 1M |
| 15 | GLM-5.1 | coding | $0.805 | $2.80 | $1.15 / $4.00 | 30% | 200K |
| 16 | Kimi K2.7 Code | coding | $0.665 | $2.80 | $0.95 / $4.00 | 30% | 256K |
| 17 | GLM-5.3 | coding | $0.98 | $3.08 | $1.40 / $4.40 | 30% | 1M |
| 18 | Qwen3.7 Plus | vision | $0.96 | $3.84 | $1.20 / $4.80 | 20% | 1M |
| 19 | Qwen3.7 MAX | reasoning | $1.36 | $4.08 | $1.70 / $5.10 | 20% | 1M |
| 20 | Qwen3.8 MAX | reasoning | $1.80 | $5.40 | $2.00 / $6.00 | 10% | 1M |
| 21 | Kimi K3 | vision | $2.40 | $12.00 | $3.00 / $15.00 | 20% | 1M |
| — | Claude Opus 4.8 (not on A2Agent) | — | — | — | $5.00 / $25.00 | — | 1M |
| — | GPT-5.5 (not on A2Agent) | — | — | — | $5.00 / $30.00 | — | 1M |
A tag says what a model is mainly built for, and models do fine outside their tag. DeepSeek V4 Pro and V4 Flash are tagged for reasoning, and both work well as coding agents. Kimi K3 is tagged for vision, and it recently topped the Frontend Code Arena.
The spread is about 180×
Every model on A2Agent costs between $0.168 and $12 per million output tokens. Twenty of the 21 cost less than $6. The two closed frontier models cost $25 and $30.
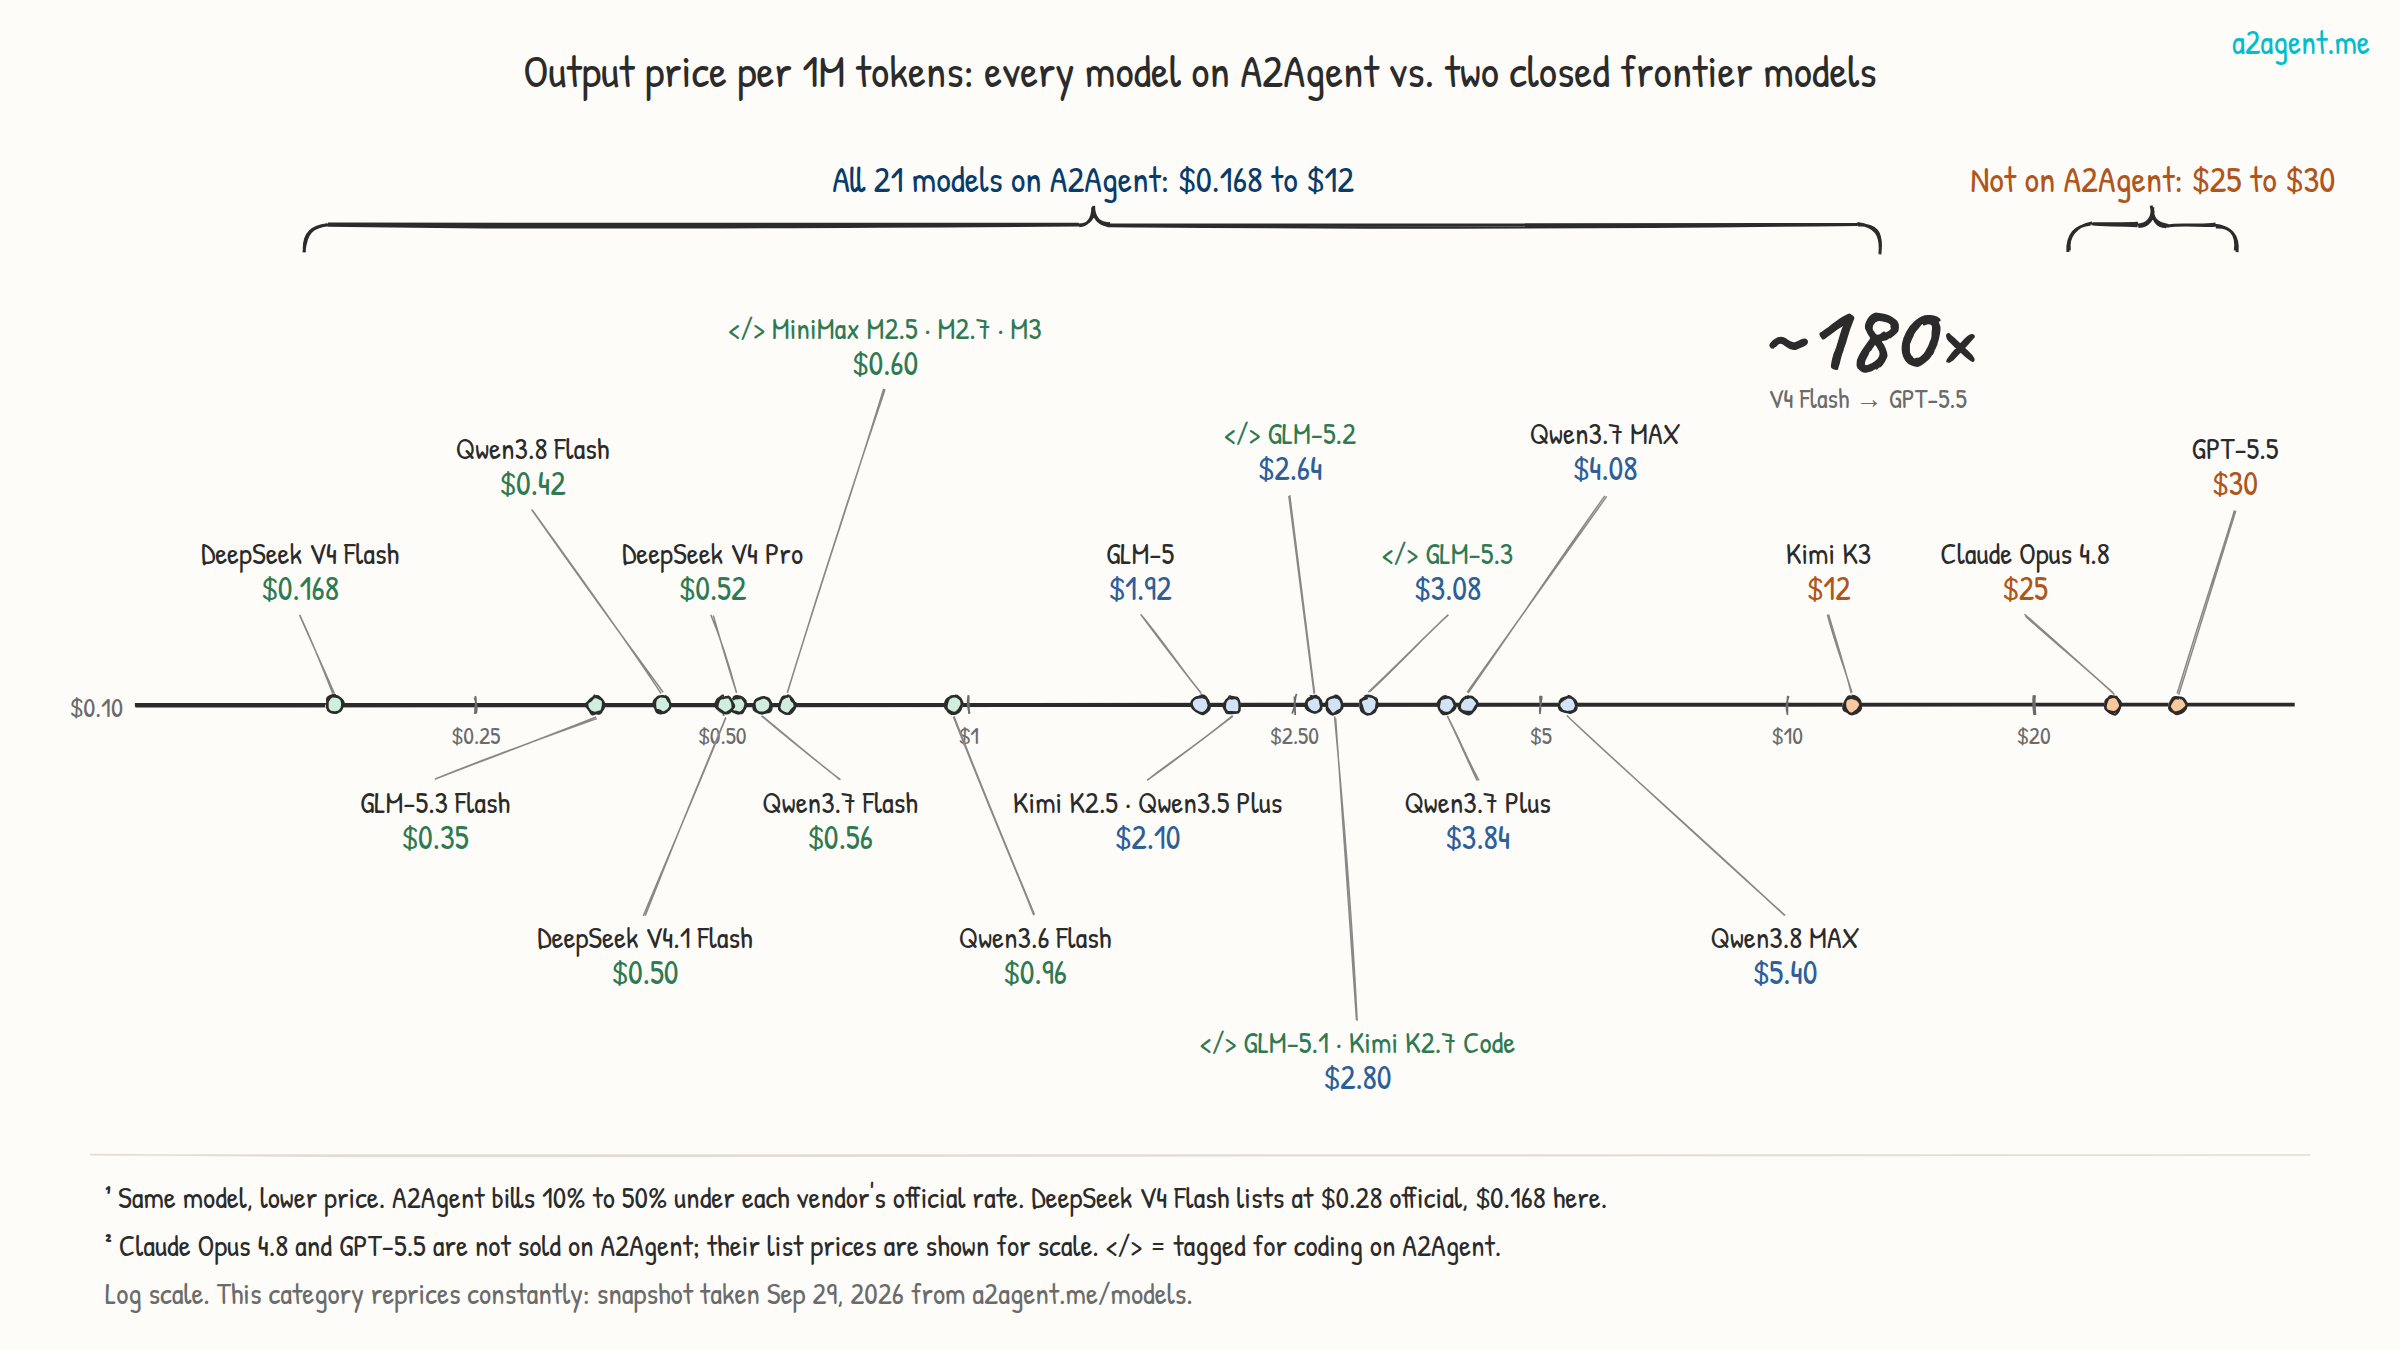
Ten models charge less than $1 per million output tokens: three from DeepSeek, four Qwen and GLM flash models, and three MiniMax models that share one price. The coding-tagged models fall into two groups. MiniMax M2.5 and M2.7 cost $0.60, and the GLM-5.x coding models and Kimi K2.7 Code cost $2.64 to $3.08.
The seller matters too. The model behind a DeepSeek V4 Flash call on A2Agent is the same one DeepSeek serves, and the bill is 40% lower. Across the catalog our discount runs from 10% to 50% below each vendor's own price, applied equally to input and output.
Why coding agents spend tokens differently
A chat request is small on both sides. You paste a snippet, ask a question, and get a paragraph back. A coding agent works in a loop. It reads files, plans, edits, runs the tests, reads the test log and tries again. Each turn usually sends the whole conversation back to the model: the system prompt, tool definitions, every file already read and every test log already seen.
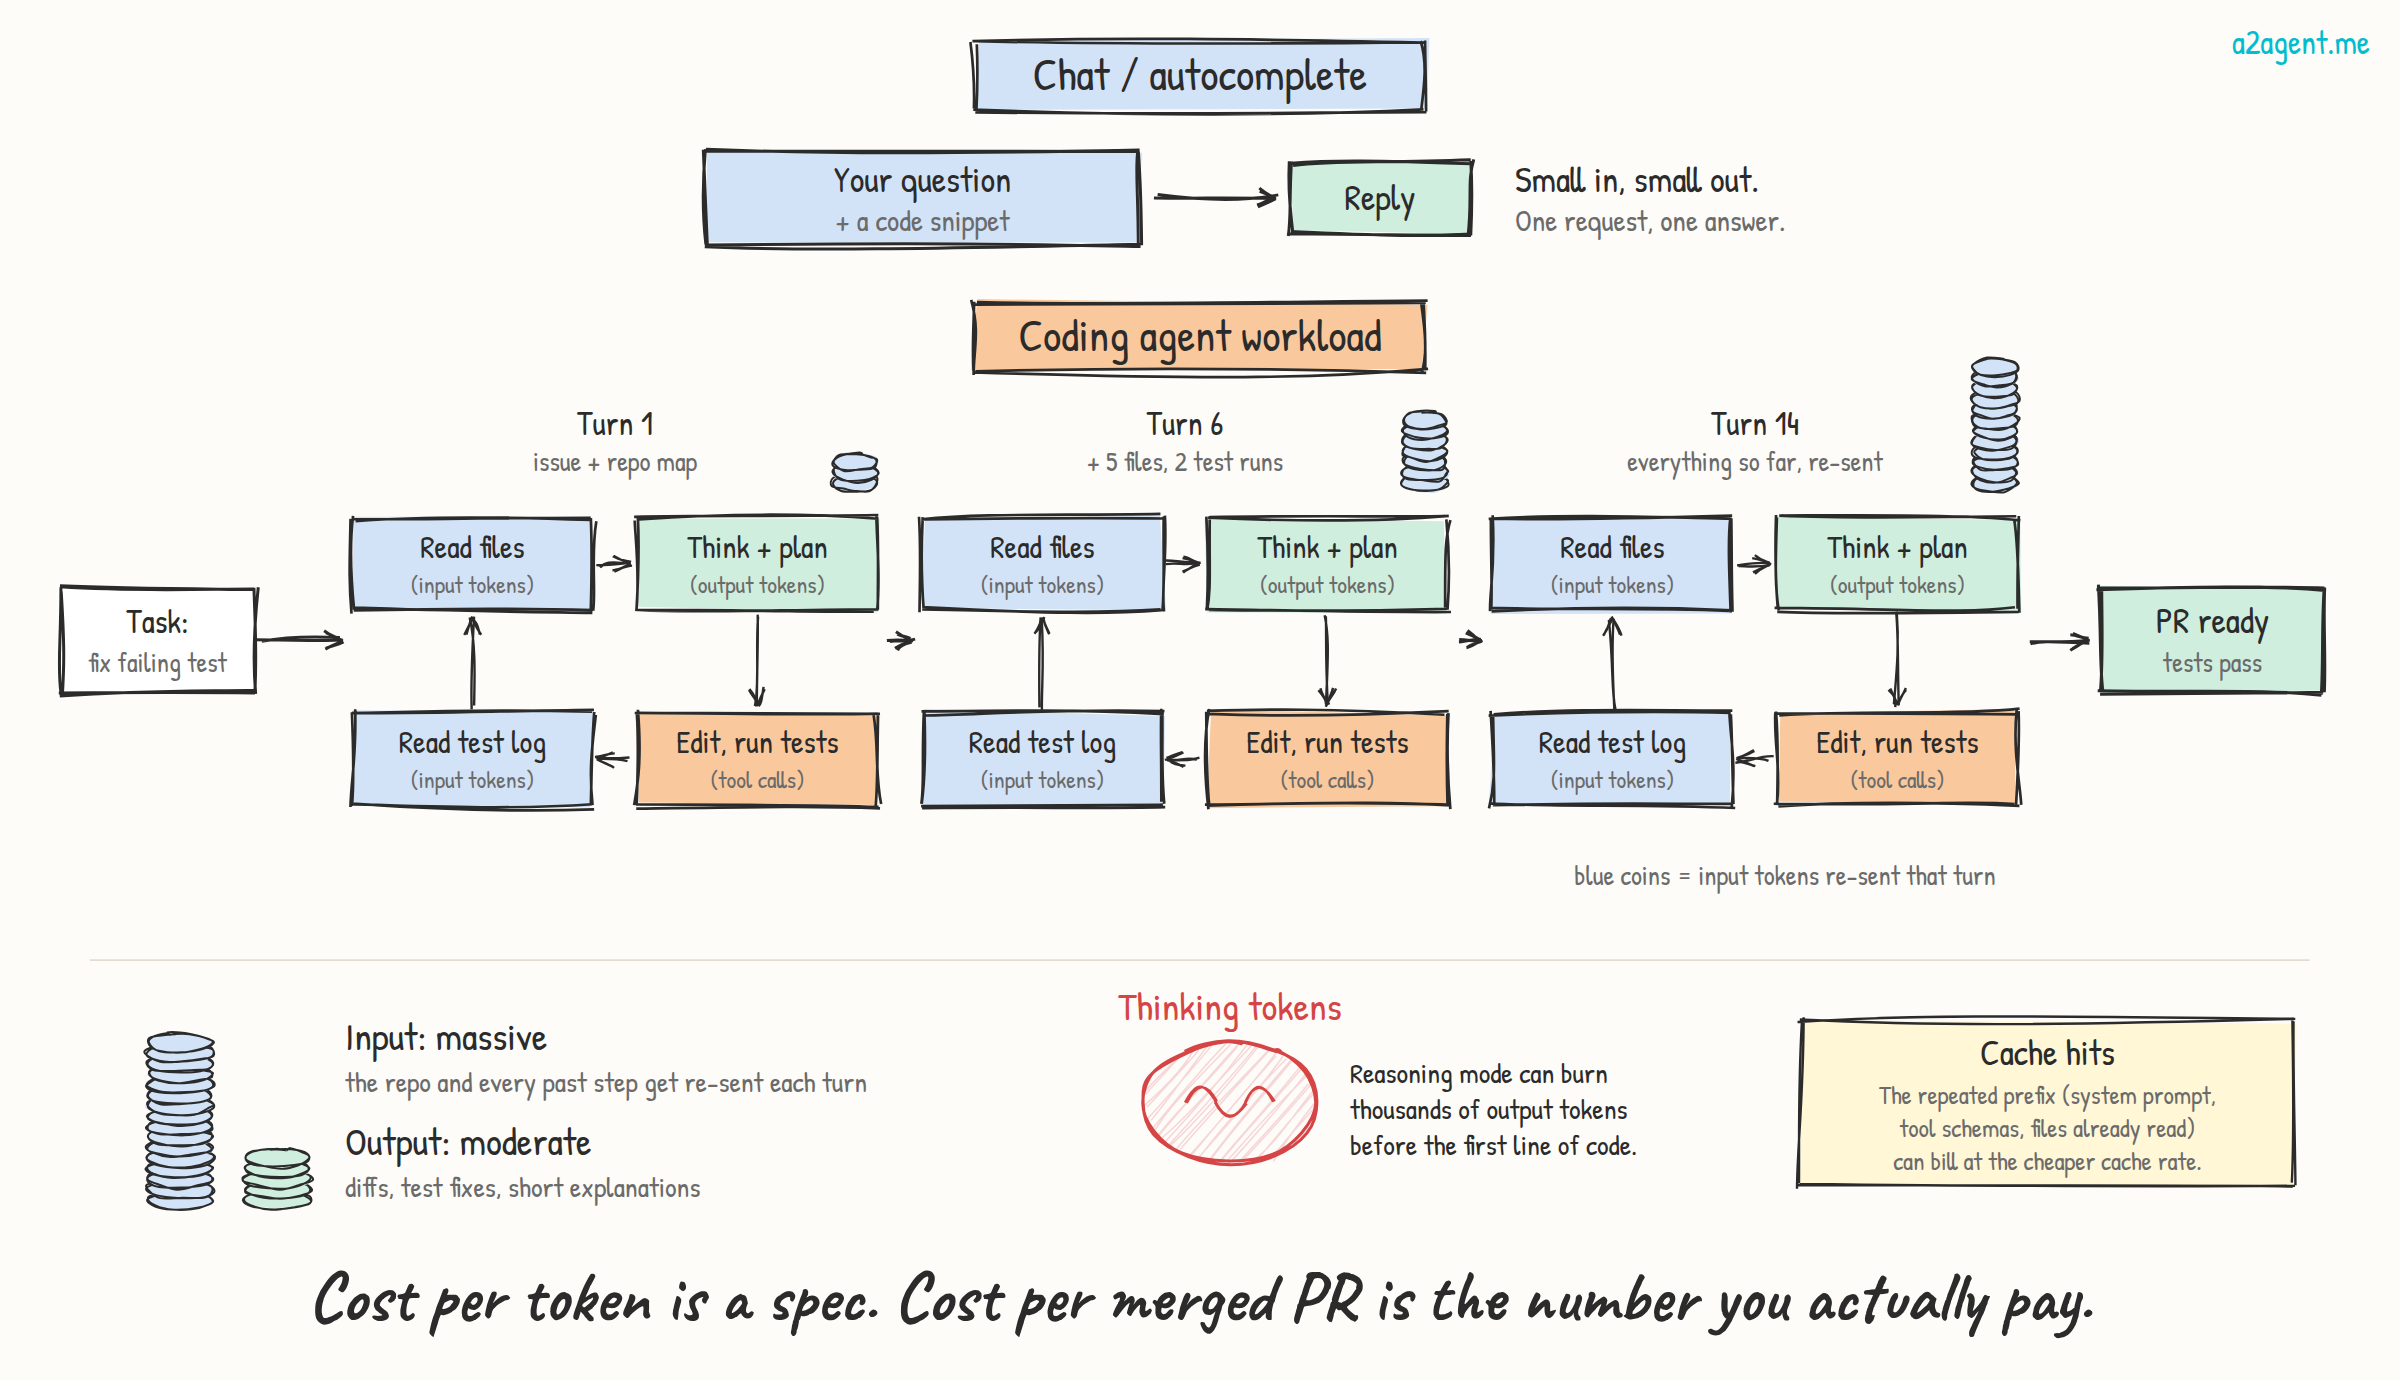
So input tokens make up most of the bill. By turn 14 the agent may be sending 200K tokens to change 30 lines. Most price comparisons lead with output prices, but for a coding model the input price deserves at least as much attention.
Thinking tokens are billed as output. In reasoning mode a model can write thousands of hidden tokens before its first line of code, so two models with the same output price can produce very different bills if one of them thinks three times as long.
Caching helps a lot here. The repeated prefix (system prompt, tool schemas, files already read) can often be billed at the provider's cheaper cache-read rate. Keep that prefix stable, and keep timestamps and random IDs out of the top of your prompt, because they break the cache.
When you compare models, the number to track is what each merged PR costs you, which the per-token price only partly predicts.
What a month of coding costs
We priced three workloads at A2Agent rates, with official prices alongside. None of these numbers include caching, so a setup with good cache hit rates will pay less.
1. Solo developer, agent in the IDE
This one assumes 40 agent tasks a day for 30 days, at about 30K input and 3K output tokens per task. That comes to 36M input and 3.6M output tokens a month, a typical load for someone working in Cline, Roo Code or Claude Code.
| Model | A2Agent / month | Official / month |
|---|---|---|
| DeepSeek V4 Flash | $3.63 | $6.05 |
| MiniMax M2.5 | $7.56 | $15.12 |
| DeepSeek V4 Pro | $11.28 | $18.79 |
| Kimi K2.7 Code | $34.02 | $48.60 |
| GLM-5.3 | $46.37 | $66.24 |
| Claude Opus 4.8 | — | $270 |
| GPT-5.5 | — | $288 |
2. PR review bot for a team
A team bot reviews 2,000 pull requests a month. Each review reads about 50K input tokens (the diff plus surrounding files) and writes 4K. That comes to 100M input and 8M output tokens a month.
| Model | A2Agent / month | Official / month |
|---|---|---|
| DeepSeek V4 Flash | $9.74 | $16.24 |
| MiniMax M2.5 | $19.80 | $39.60 |
| DeepSeek V4 Pro | $30.28 | $50.46 |
| Kimi K2.7 Code | $88.90 | $127.00 |
| GLM-5.3 | $122.64 | $175.20 |
| Claude Opus 4.8 | — | $700 |
| GPT-5.5 | — | $740 |
3. Autonomous coding agent in production
Here the agent takes an issue all the way to a PR, 500 times a month, at about 200K input and 40K output tokens per run. That comes to 100M input and 20M output tokens a month.
| Model | A2Agent / month | Official / month |
|---|---|---|
| DeepSeek V4 Flash | $11.76 | $19.60 |
| MiniMax M2.5 | $27.00 | $54.00 |
| DeepSeek V4 Pro | $36.54 | $60.90 |
| Kimi K2.7 Code | $122.50 | $175.00 |
| GLM-5.3 | $159.60 | $228.00 |
| Kimi K3 | $480.00 | $600.00 |
| Claude Opus 4.8 | — | $1,000 |
| GPT-5.5 | — | $1,100 |
In the third scenario Opus costs about 85 times as much as V4 Flash, and GPT-5.5 about 94 times as much. That is well under the 180× gap in output prices, because this workload is mostly input and input prices sit closer together.
Is the cheap model good enough?
For most coding work, yes. In our comparison of closed and open-source LLMs we looked at two leaderboards that measure different things.
Vals Index scores how often a model completes real tasks in finance, law, coding and agent workflows. The top closed model completes 68.83%. Three models you can call on A2Agent reach about 83% to 84% of that: DeepSeek V4.1 Flash (57.86%), Kimi K3 (57.81%) and GLM-5.3 (56.97%). DeepSeek V4.1 Flash was also the cheapest model on the board per completed task, at about $0.30.
Arena's Image-to-WebDev leaderboard rates front-end code built from a design. Qwen3.8 MAX scores 1,639 there and GLM-5.3 Flash 1,588, about 95% and 92% of the leader's 1,733. On the Frontend Code Arena, Kimi K3 took first place in July with 1,679.
The closed frontier still leads, by roughly 16% to 25% on completed tasks and by single digits on user preference. Per output token, Opus and GPT-5.5 cost about 2 times (against Kimi K3) to 86 times (against GLM-5.3 Flash) as much as those models. We'd pay that premium for a tricky migration or a subtle concurrency bug, or for a change nobody will review closely. Renaming, writing tests, fixing lint errors, small features and diff review make up most coding work, and there the extra quality rarely changes the result.
A leaderboard score won't tell you how reliably a model calls tools, whether it follows your repo's conventions, or how long it likes to think. Every model on A2Agent sits behind the same API key, so it takes an afternoon to run your own tasks through two or three candidates before you commit.
Route by task instead of picking one model
The cheapest setup is usually a mix of models. On A2Agent one API key covers all of them, and switching means changing the model string.
| Coding job | Suggested model | Why |
|---|---|---|
| Commit messages, docstrings, log triage, "which test failed and why" | DeepSeek V4 Flash, Qwen3.8 Flash, GLM-5.3 Flash | Output under $0.50 per million; 1M context |
| Everyday edits in Cline, Roo Code or Kilo Code | MiniMax M2.5 / M2.7 | Cheapest coding-tagged models at $0.60 output |
| Long multi-step agent runs | MiniMax M3, GLM-5 | Tagged for agents; M3 has a 1M window at $0.60 output |
| Hard debugging, careful reasoning | DeepSeek V4 Pro | Strong reasoning at $0.522 output, 1M context |
| Whole-repository prompts | GLM-5.3, GLM-5.2 | Coding-tagged with a 1M window |
| Coding agent inside a 256K budget | Kimi K2.7 Code | Coding-tagged, with a lower input price than the GLM-5.x coding models |
| Frontend and UI generation | Kimi K3 | Led the Frontend Code Arena at 1,679 in July 2026 |
Switching takes two settings
A2Agent accepts both the OpenAI and the Anthropic API formats, so most coding tools only need a base URL and a key.
OpenAI-compatible tools and SDKs (Cline, Roo Code, Kilo Code, Cursor, Codex CLI):
from openai import OpenAI

client = OpenAI(
    api_key="YOUR_A2AGENT_KEY",
    base_url="https://api.a2agent.me/v1",
)

resp = client.chat.completions.create(
    model="minimax-m2.5",  # or deepseek-v4-flash, glm-5.3, kimi-k2.7-code ...
    messages=[{"role": "user", "content": "Write a unit test for parse_date()."}],
)
print(resp.choices[0].message.content)
Claude Code, through the Anthropic Messages API:
export ANTHROPIC_BASE_URL="https://api.a2agent.me"
export ANTHROPIC_AUTH_TOKEN="YOUR_A2AGENT_KEY"
There are step-by-step guides for Claude Code, Codex CLI, Cline, Roo Code, Kilo Code and Cursor.
Check the context window before you switch. Our models range from 200K to 1M, and if your agent packs whole repositories into the prompt, a 200K model will cut them short. Use exact model IDs, since kimi-k2.7-code and kimi-k2.5 are different models at different prices. Reasoning modes and effort controls also differ from vendor to vendor. Cap them where you can, because thinking tokens are billed as output.
Which one should you pick?
- Under $10 a month: DeepSeek V4 Flash. It handled the solo-developer workload for $3.63.
- Under $50 a month: MiniMax M2.5 as the main coding model, with V4 Flash for small calls and V4 Pro when something needs more careful reasoning.
- Around $150 a month for a team: Kimi K2.7 Code or GLM-5.3 for agent runs, with the cheaper models handling everything else.
- If one task really needs the closed frontier, send that task to Opus or GPT-5.5 and keep the rest on cheaper models.
A2Agent is pay-as-you-go with no subscription, and your balance doesn't expire. Current prices are always in the model catalog.
Sources
- A2Agent model catalog and live prices (snapshot taken September 29, 2026)
- A2Agent: Closed vs. Open-Source LLMs: Current State, Capability Gap, and How to Choose (Vals Index and Arena Image-to-WebDev figures)
- A2Agent: Kimi-K3's Frontend Win Complicates the U.S.-China AI Narrative
- A2Agent integration guides for Claude Code, Codex CLI, Cline, Roo Code, Kilo Code and Cursor
- Claude Opus 4.8 and GPT-5.5 prices are the vendors' public API list prices as of September 2026.